
Array Foreign Key - Bulk Update
Select and export the array foreign key metadata to a .csv file, edit in a spreadsheet like Google Sheets or Excel, then perform a bulk update in DataPancake.
Array Foreign Key - Bulk Update
Ensure you have completed the Array Foreign Key - Initialization guide.
This guide explains how to export foreign key metadata, edit the metadata in a spreadsheet, and apply the changes through a CSV bulk update.
The examples use the sample Real Estate data source. The exact data source ID and available child tables may vary by environment.
Open a new SQL worksheet in Snowflake
Open Snowsight and create a new SQL worksheet.
Select a role, warehouse, database, and schema with access to the DataPancake application and the Snowflake stage used for bulk-update files.
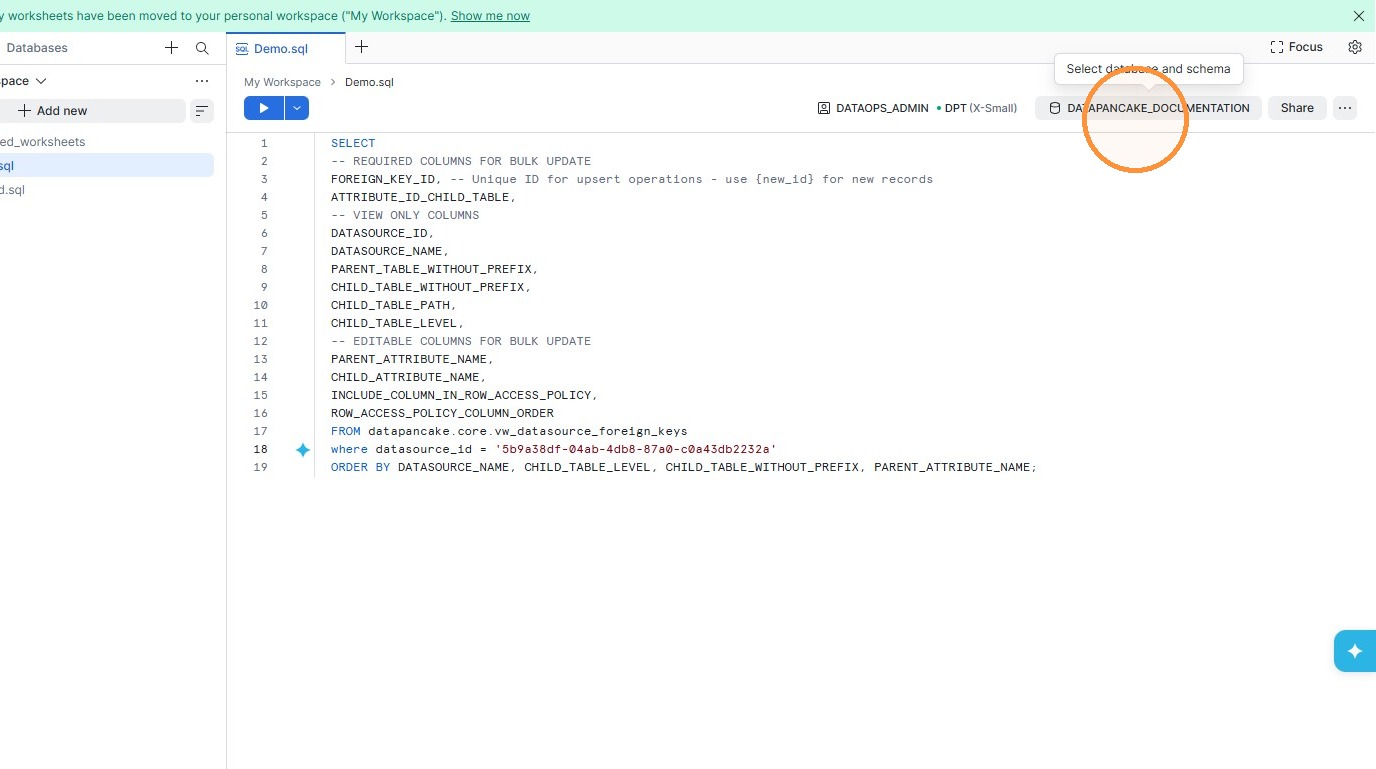
Export the foreign key metadata
Run the following query to retrieve foreign key metadata from DATAPANCAKE.CORE.VW_DATASOURCE_FOREIGN_KEYS.
For the Real Estate demonstration, filter the query to the sample Real Estate data source in your environment.
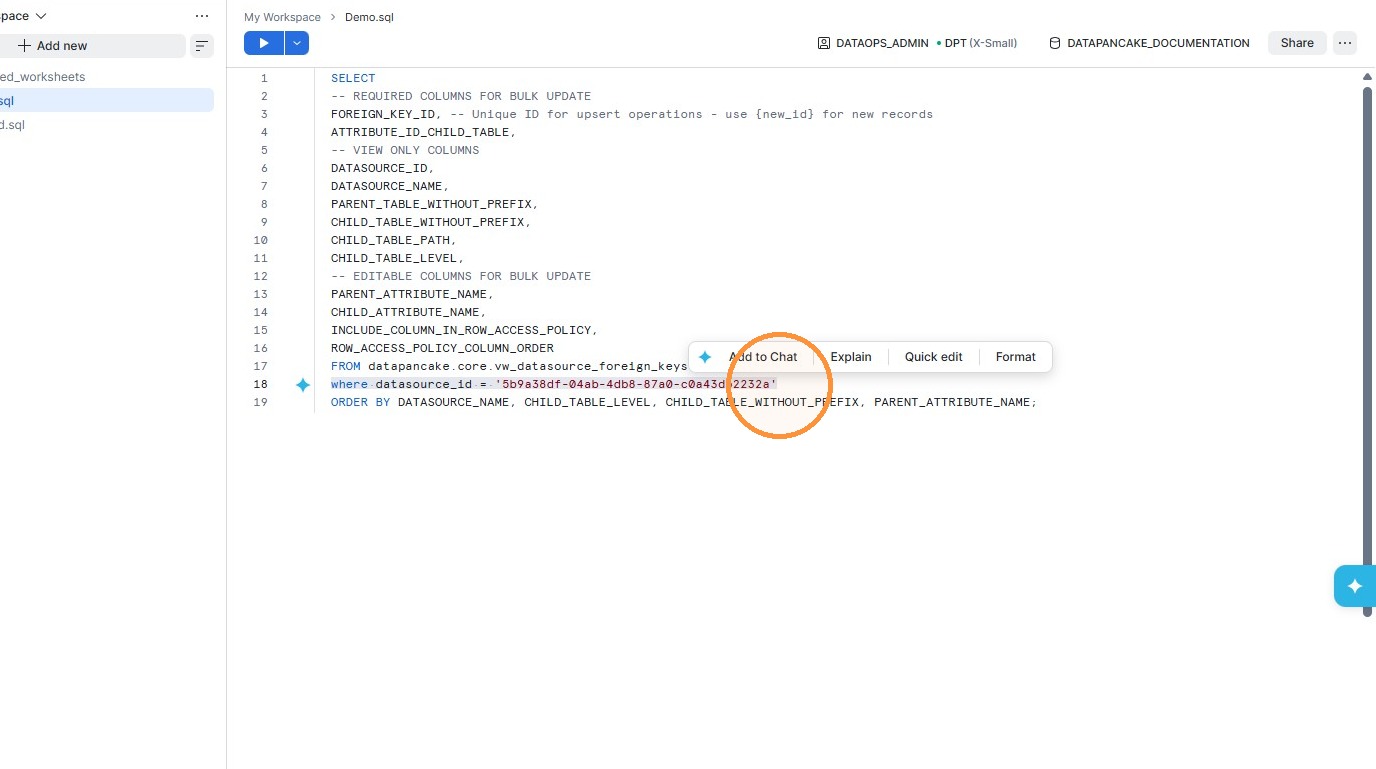
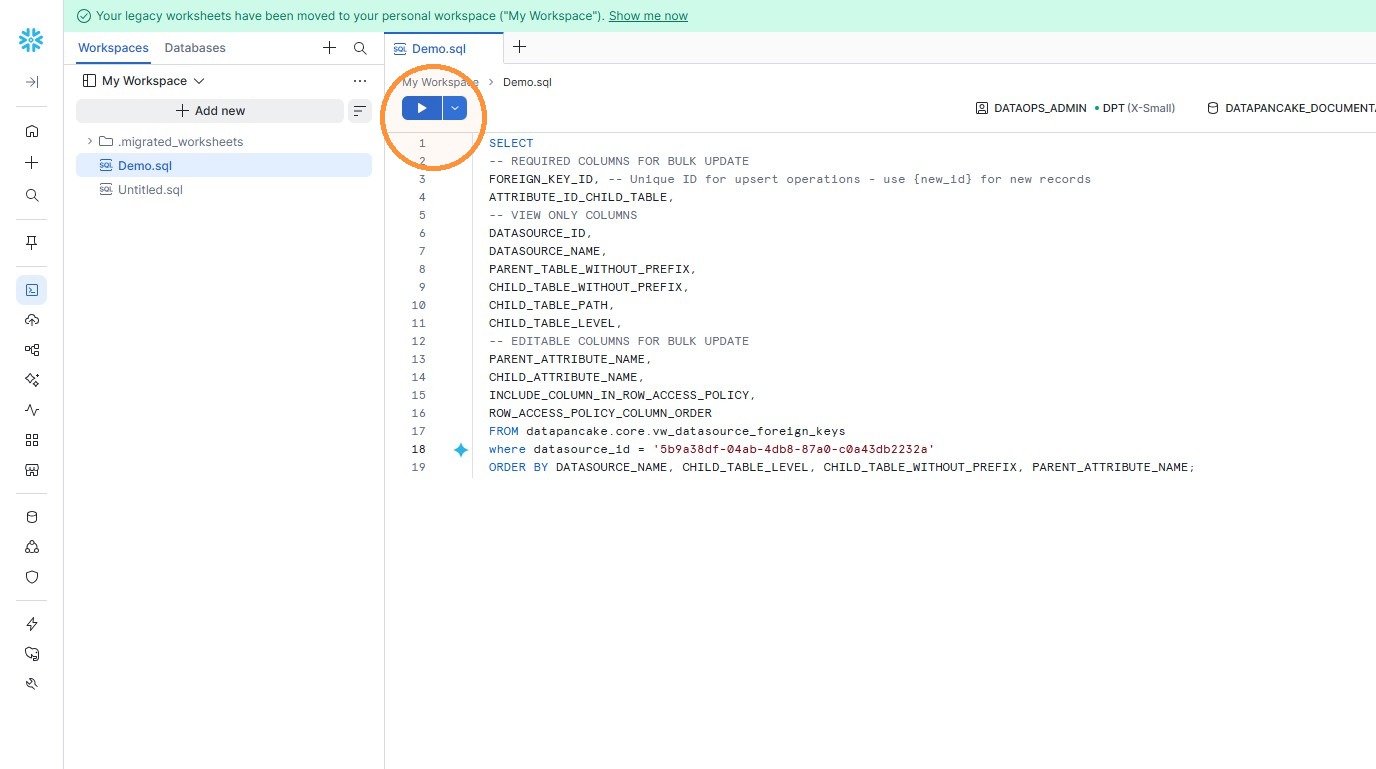
Run the query and review the results
Execute the query.
Confirm that the results contain the Real Estate data source and its child tables.
Use the following columns to identify each child table:
CHILD_TABLE_WITHOUT_PREFIXCHILD_TABLE_PATHCHILD_TABLE_LEVELATTRIBUTE_ID_CHILD_TABLE
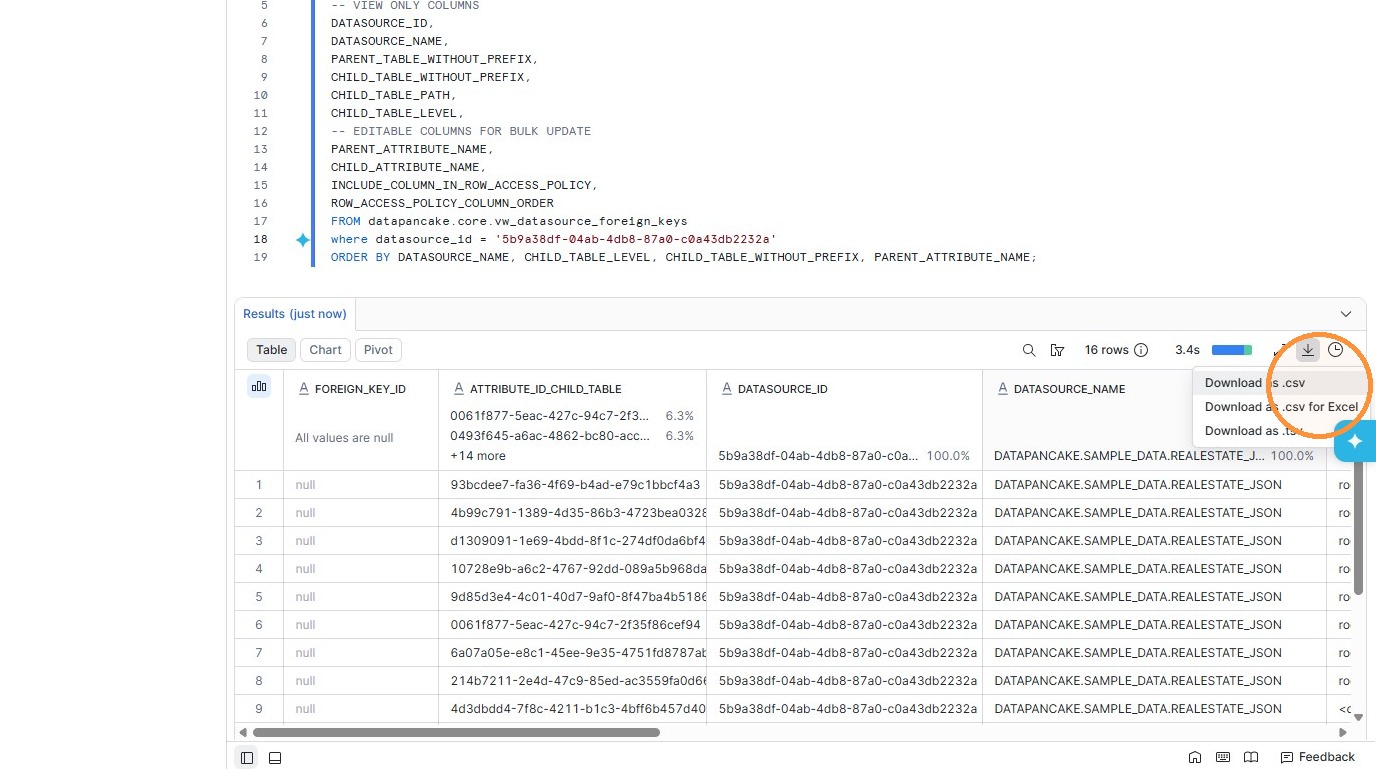
Download the results as a CSV file
Download the query results as a .csv file.
Open the CSV file
Open the downloaded file in Excel, Google Sheets, or another spreadsheet editor that preserves CSV formatting.
Confirm that the header row contains all exported columns.
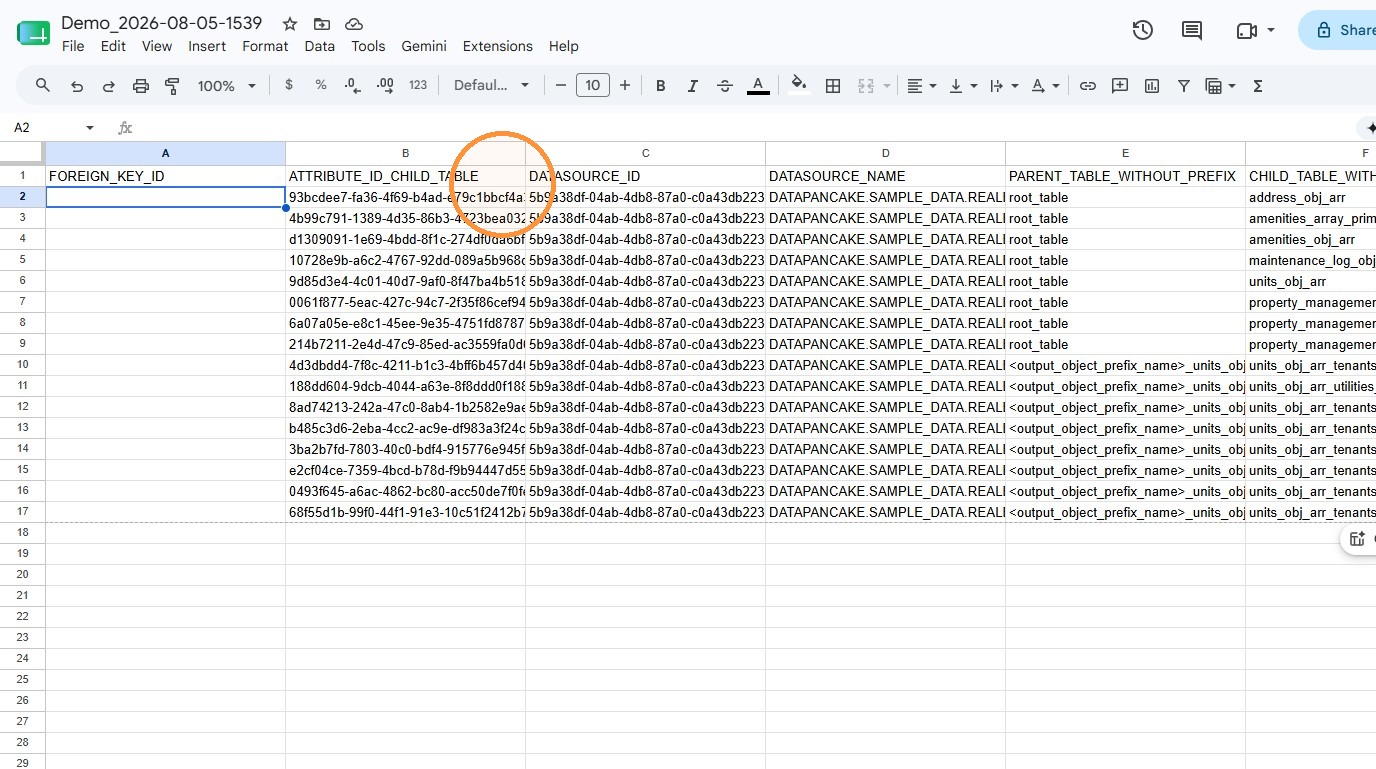
Review the CSV columns
Column
Usage
FOREIGN_KEY_ID
Preserve the existing identifier when updating a record. Enter {new_id} when creating a new foreign key.
ATTRIBUTE_ID_CHILD_TABLE
Required identifier for the child table attribute. Preserve the exported value.
DATASOURCE_ID
View-only data source identifier. Do not edit.
DATASOURCE_NAME
View-only data source name. Do not edit.
PARENT_TABLE_WITHOUT_PREFIX
View-only parent table name. Do not edit.
CHILD_TABLE_WITHOUT_PREFIX
View-only child table name. Do not edit.
CHILD_TABLE_PATH
View-only path that identifies the child table within the source structure. Do not edit.
CHILD_TABLE_LEVEL
View-only nesting level of the child table. Do not edit.
PARENT_ATTRIBUTE_NAME
Parent attribute whose value should be added to the child table.
CHILD_ATTRIBUTE_NAME
Name of the foreign key column created in the child table.
INCLUDE_COLUMN_IN_ROW_ACCESS_POLICY
Enter TRUE or FALSE to control whether the generated child-table column is included in the row access policy.
ROW_ACCESS_POLICY_COLUMN_ORDER
Enter the column's position in the row access policy when applicable. Leave blank when the column is not included in the policy.
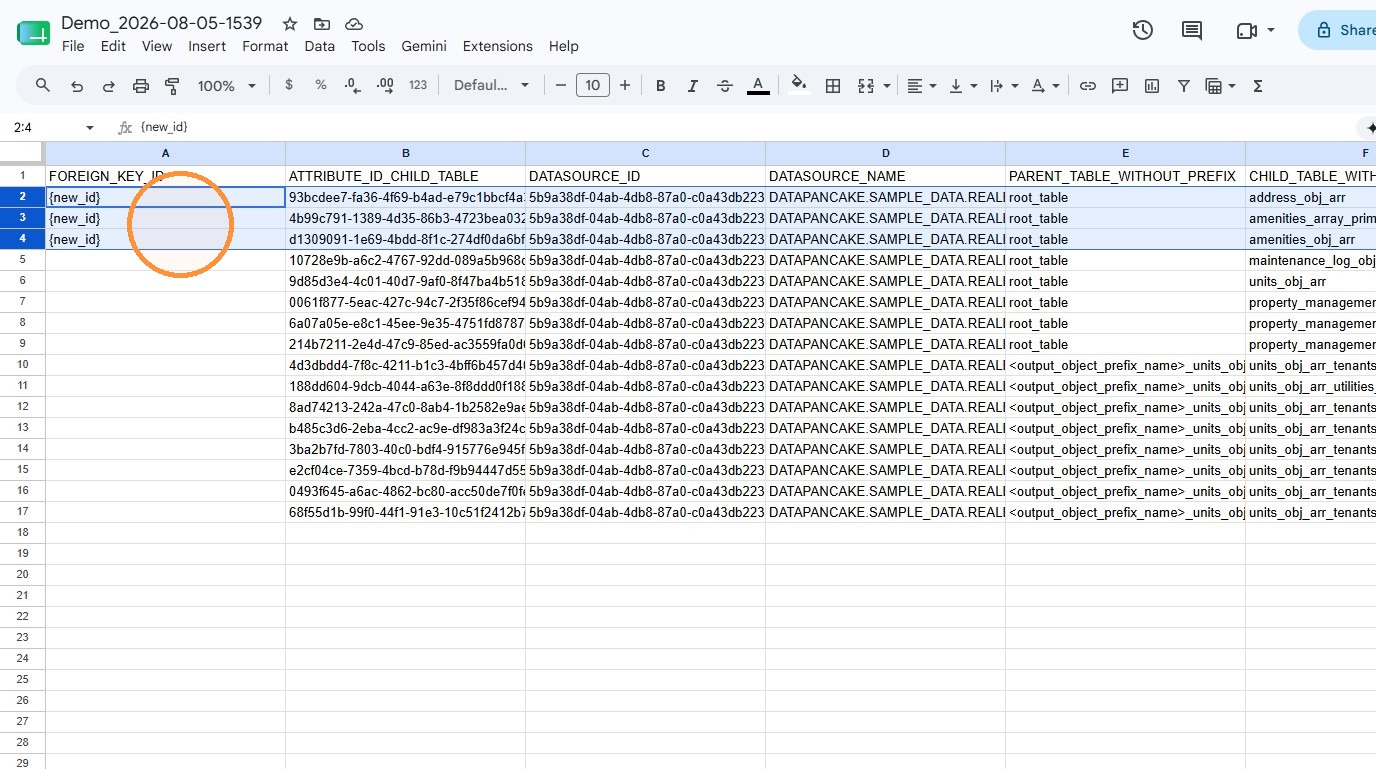
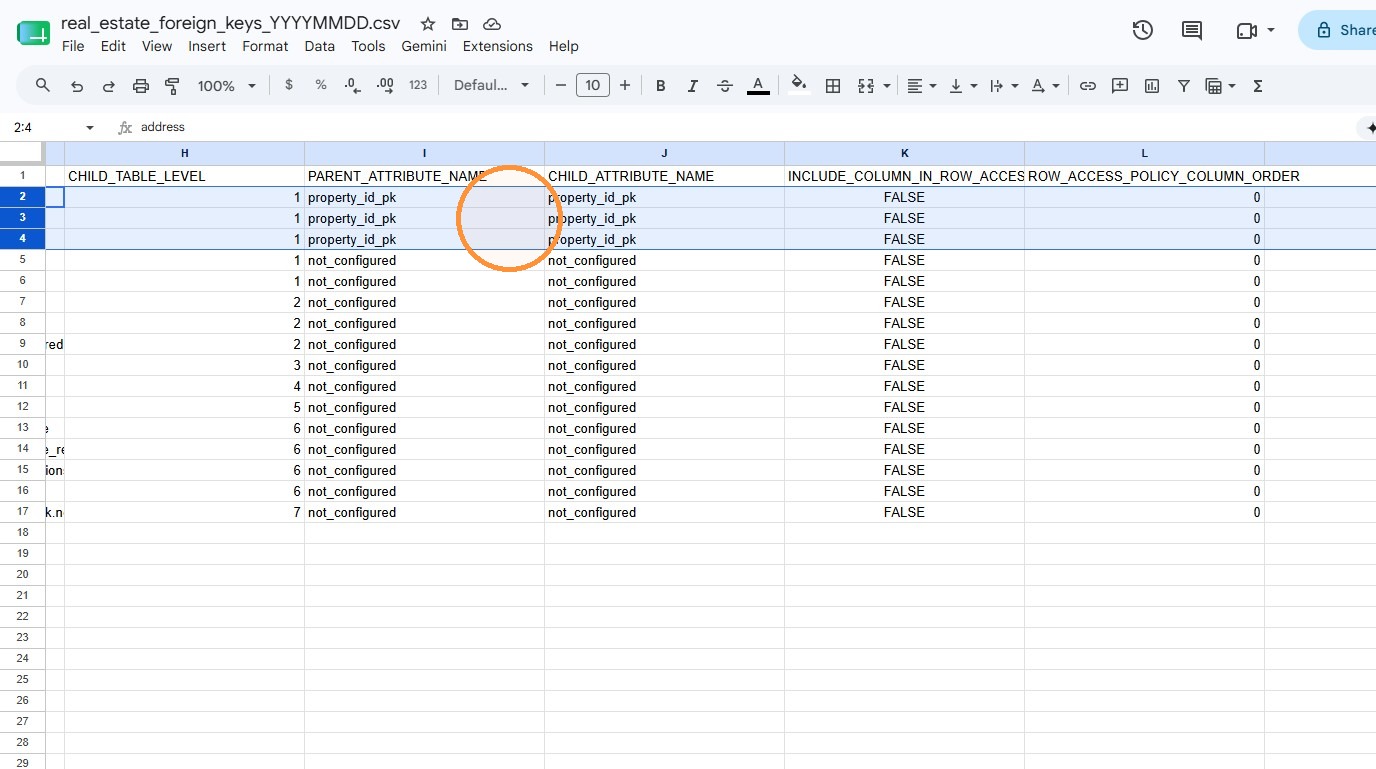
Add property_id_pk to selected Real Estate child tables
For this demonstration, select a few of the Real Estate child tables that should receive the parent property's identifier.
For each selected child table:
Enter
{new_id}inFOREIGN_KEY_ID.Preserve the exported
ATTRIBUTE_ID_CHILD_TABLE.Enter
property_id_pkinPARENT_ATTRIBUTE_NAME.Enter
property_id_pkinCHILD_ATTRIBUTE_NAME.Enter
FALSEinINCLUDE_COLUMN_IN_ROW_ACCESS_POLICY.Leave
ROW_ACCESS_POLICY_COLUMN_ORDERblank.
Example:
FOREIGN_KEY_ID
ATTRIBUTE_ID_CHILD_TABLE
CHILD_TABLE_WITHOUT_PREFIX
PARENT_ATTRIBUTE_NAME
CHILD_ATTRIBUTE_NAME
INCLUDE_COLUMN_IN_ROW_ACCESS_POLICY
ROW_ACCESS_POLICY_COLUMN_ORDER
{new_id}
Preserve exported value
First selected child table
property_id_pk
property_id_pk
FALSE
{new_id}
Preserve exported value
Second selected child table
property_id_pk
property_id_pk
FALSE
{new_id}
Preserve exported value
Third selected child table
property_id_pk
property_id_pk
FALSE
Save the CSV file
Save or download the edited spreadsheet as a CSV file.
Use a descriptive filename, such as:
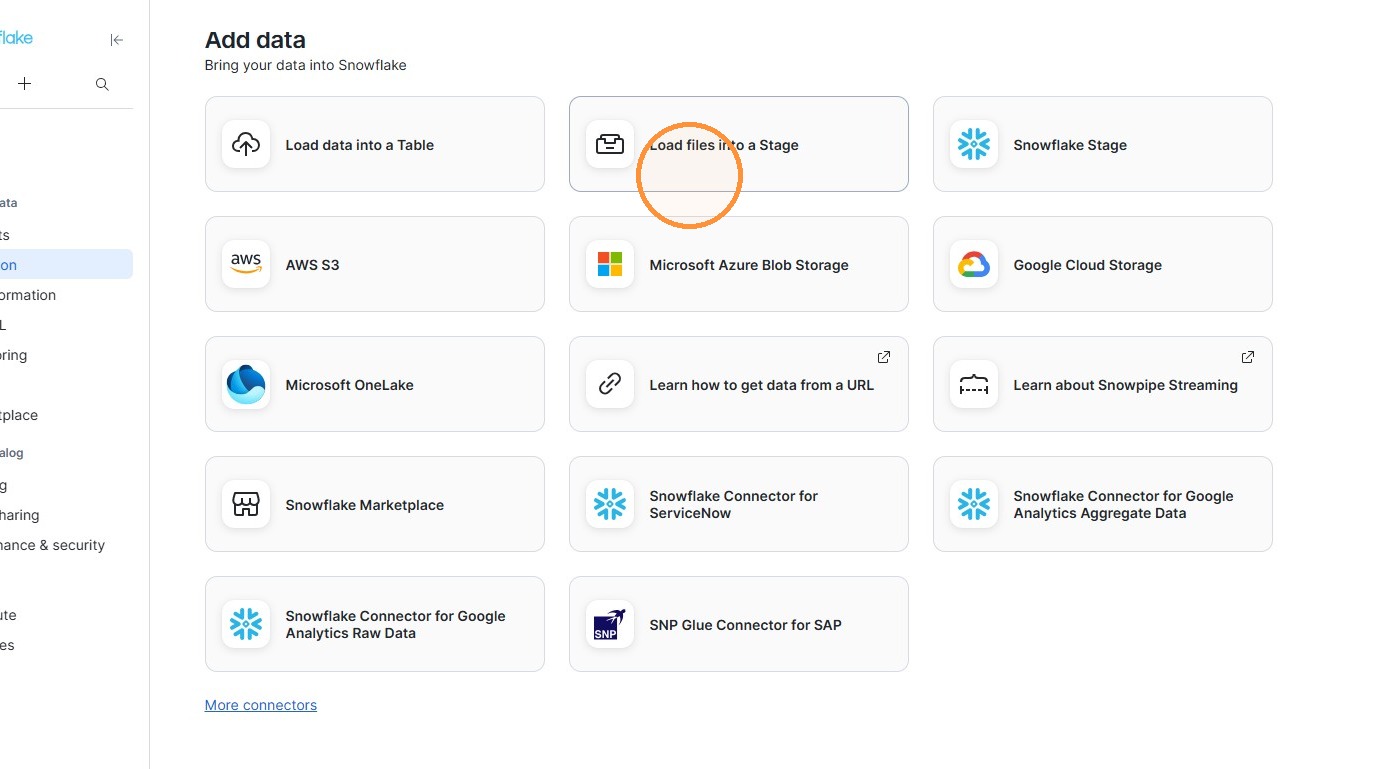
Upload the CSV to a Snowflake stage
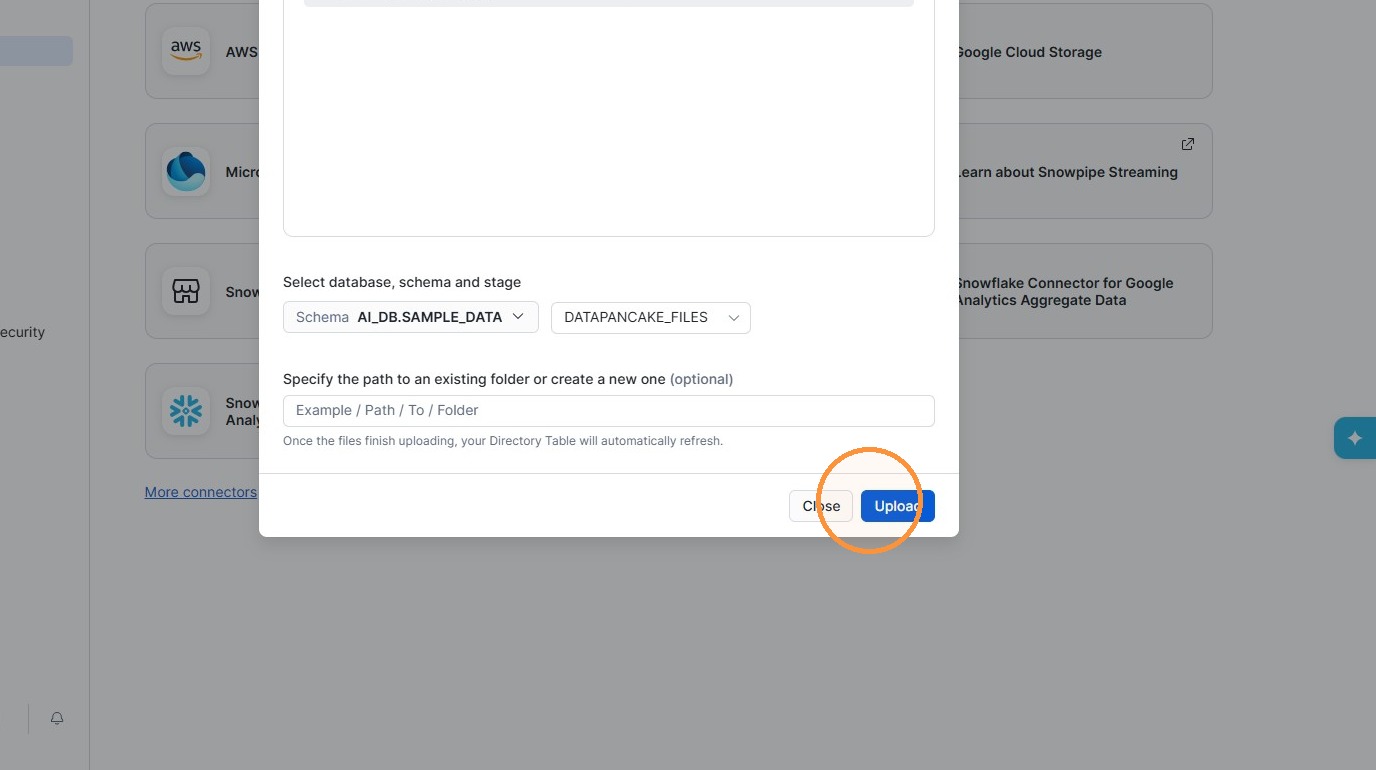
In Snowflake, navigate to the database, schema, and stage used for DataPancake bulk-update files.
Select + Files or the equivalent upload action and upload the edited CSV.
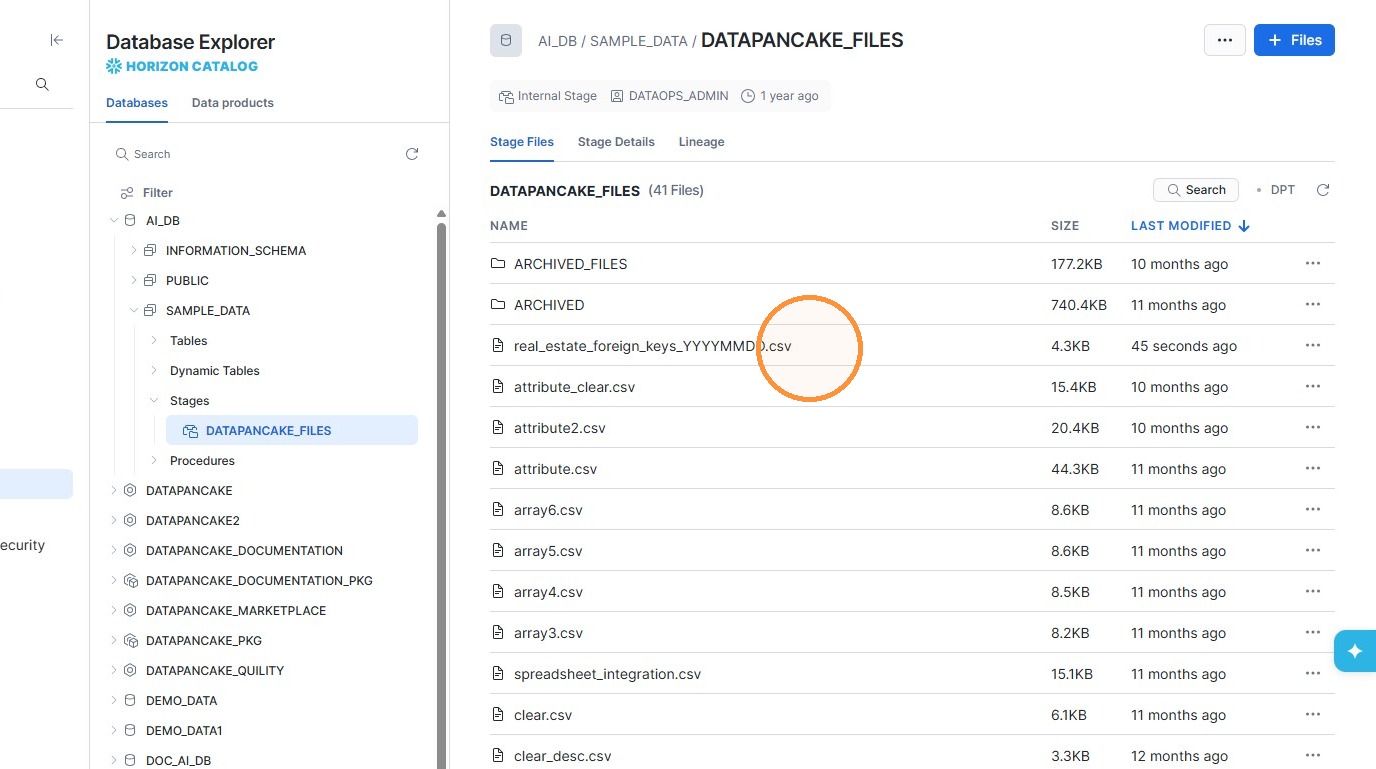
Verify the staged filename
Confirm that the uploaded CSV appears in the stage.
Note the exact stage path and filename. You will use both values in the stored procedure call.
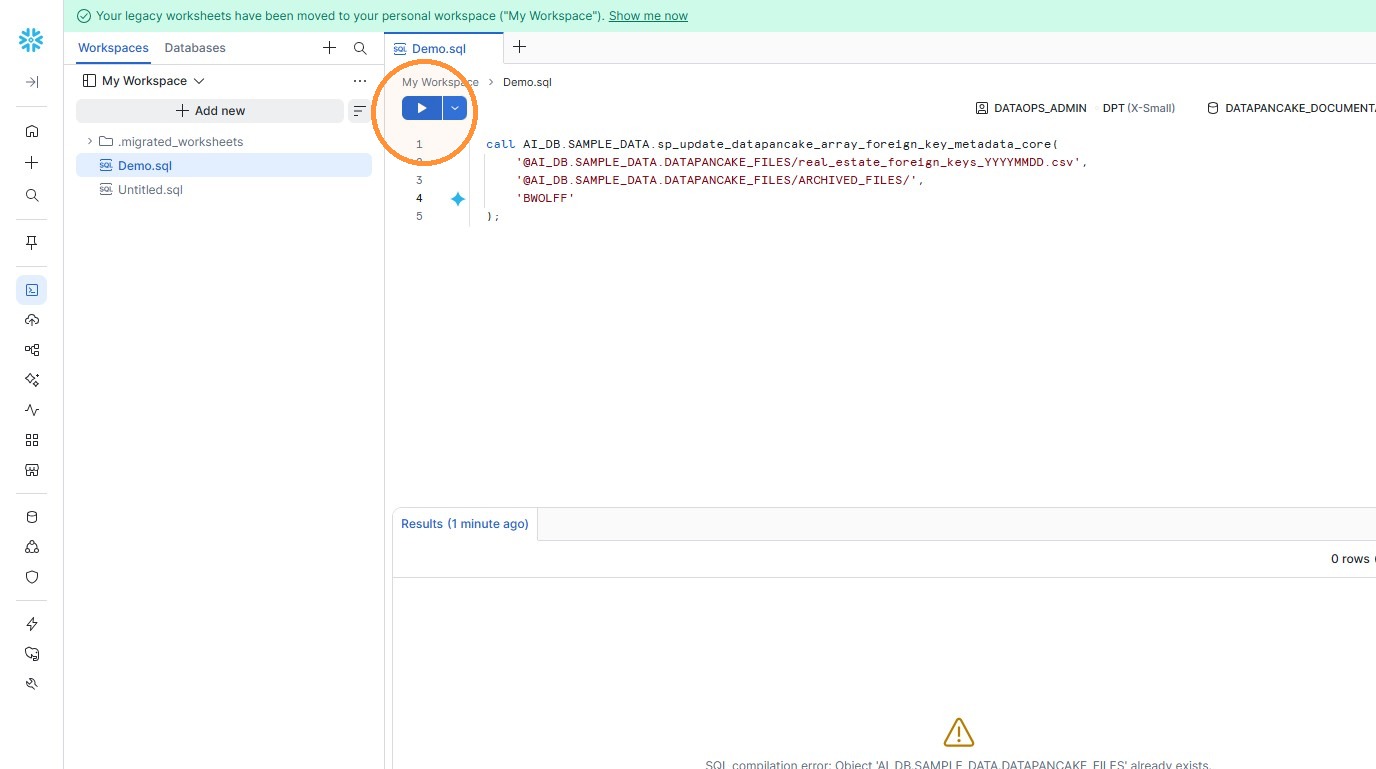
Run the bulk update stored procedure
Run the same array foreign key bulk-update procedure used for existing foreign key files.
Replace the placeholders with values for your environment.
Example structure:
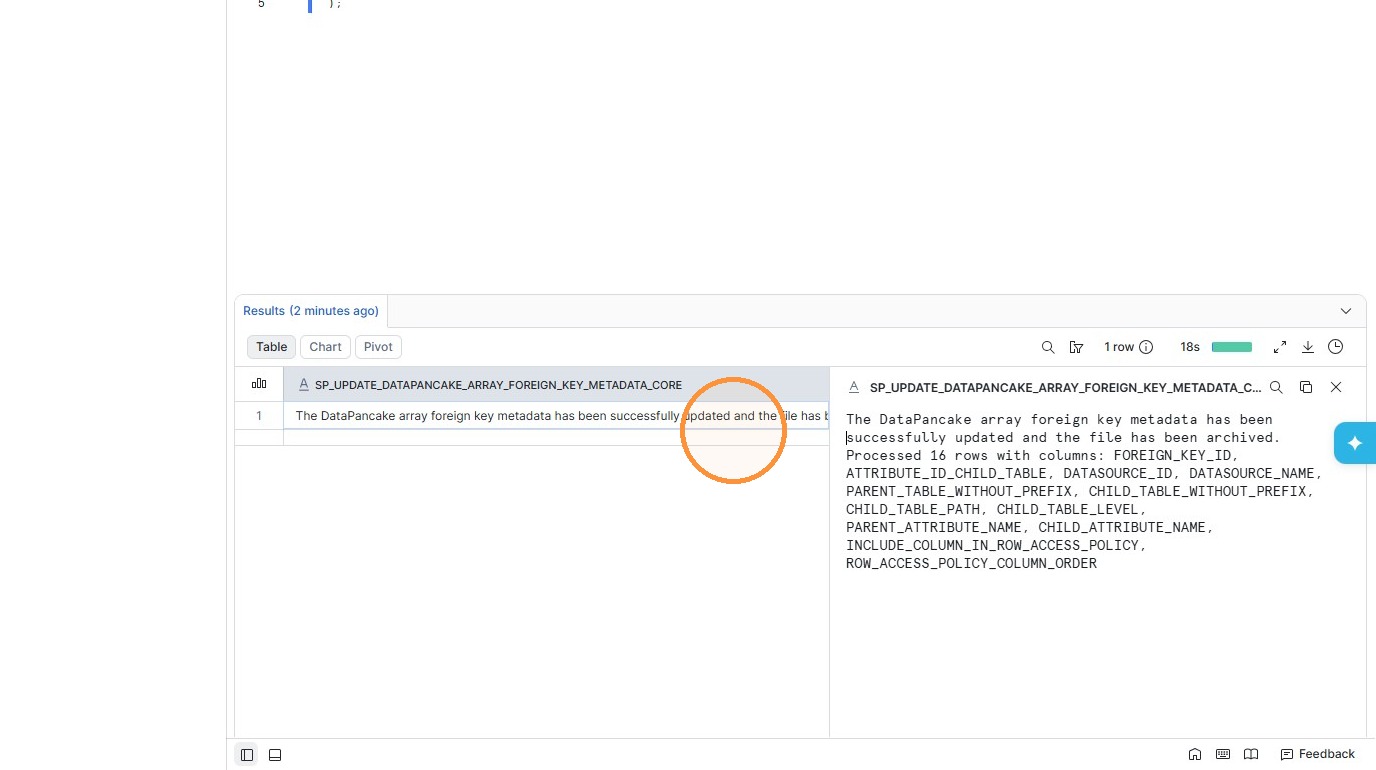
Review the returned processing message
Execute the stored procedure call.
The procedure returns a processing message after it evaluates the uploaded file. Review the complete returned message and confirm that the file was processed successfully.
The screenshot for this step should capture the full message returned by the current version of the stored procedure.
Confirm that the file was archived
After a successful update, confirm that the processed CSV was moved to the configured archive folder.
The file should:
Appear in the archive folder.
No longer appear in its original stage location.
Verify the new foreign keys
Rerun the export query using the same Real Estate data source filter.
For each child table updated in the CSV, confirm that:
FOREIGN_KEY_IDnow contains a generated identifier instead of{new_id}.ATTRIBUTE_ID_CHILD_TABLEidentifies the expected child table attribute.PARENT_ATTRIBUTE_NAMEisproperty_id_pk.CHILD_ATTRIBUTE_NAMEisproperty_id_pk.INCLUDE_COLUMN_IN_ROW_ACCESS_POLICYisFALSE.The correct child table is shown in
CHILD_TABLE_WITHOUT_PREFIXandCHILD_TABLE_PATH.
Optional: Review the integration process
You can also review the DataPancake integration process log.
Replace <snowflake_username> with the username passed to the bulk-update procedure.
Review the latest entry associated with the uploaded CSV.
Troubleshooting
The staged file could not be found
Confirm that:
The file was uploaded successfully.
The stage path is correct.
The filename in the procedure call exactly matches the staged filename.
The filename does not contain a duplicated
.csvextension.The active Snowflake role has access to the stage.
You can list the staged files to confirm the exact filename:
A new foreign key was not created
Confirm that:
FOREIGN_KEY_IDcontains exactly{new_id}.ATTRIBUTE_ID_CHILD_TABLEcontains the original exported identifier.PARENT_ATTRIBUTE_NAMEcontainsproperty_id_pk.CHILD_ATTRIBUTE_NAMEcontainsproperty_id_pk.The required column headers were not renamed.
The intended child table row was edited.
An existing foreign key was duplicated
Use {new_id} only when creating a new foreign key.
When updating an existing relationship, preserve the generated value already present in FOREIGN_KEY_ID.
The wrong child table was updated
Use the following view-only fields together to identify the intended table before editing:
CHILD_TABLE_WITHOUT_PREFIXCHILD_TABLE_PATHCHILD_TABLE_LEVELATTRIBUTE_ID_CHILD_TABLE
Do not rely on the child table name alone when similarly named tables exist at different nesting levels.
The row access policy configuration was not applied
Confirm that:
INCLUDE_COLUMN_IN_ROW_ACCESS_POLICYcontainsTRUEorFALSE.ROW_ACCESS_POLICY_COLUMN_ORDERis populated when required.The data source has the required security policy features enabled.
The configured policy supports the selected child-table column.
Last updated
Was this helpful?